ACTUAL CODEX RUNS · INDEPENDENT STATE VERIFICATION
Does Smart365 improve an agent’s work?
In this controlled pilot, Smart365 had 31.7% higher mean token use and 49.8% higher median confirmation time.
18 measured runs · gpt-5.3-codex · 3 business tasks · Complete controlled pilot
Independently verified
9/9 → 9/9
Control → Smart365Mean token use
56,397 → 74,296
Input + output, cached input included onceMedian confirmed time
13.13s → 19.68s
Successful runs onlyCompare the same task
Bars show measured mean tokens per run. They do not measure billing cost.
| Metric | Codex browser only | Codex + Smart365 |
|---|---|---|
| Verified jobs | 9/9 | 9/9 |
| Mean tokens / run (input + output) | 56,397 | 74,296 |
| Mean input tokens | 55,820 | 73,383 |
| Mean cached input tokens (included above) | 47,844 | 60,416 |
| Mean uncached input tokens | 7,976 | 12,967 |
| Mean output tokens | 577 | 913 |
| Median Codex execution (seconds) | 12.84 | 19.56 |
| Median time to independently confirmed state (seconds) | 13.13 | 19.68 |
| Mean account setup seconds (outside timed task) | 0.27 | 2.09 |
| Mean model tool calls / run | 6.1 | 6.6 |
| Mean browser / Smart365 MCP calls / run | 6.1 | 6.6 |
| Smart365 provider calls (total, separate from model calls) | 0 | 36 |
| Tool errors | 0 | 0 |
| Runs with verification mismatch and recovery | 0 | 1 |
| Timed-out runs | 0 | 0 |
| Runs with confirmed licensed SDK initialization | 0 | 9 |
| Additional SDK chatbot model requests | 0 | 0 |
Per-task measurements
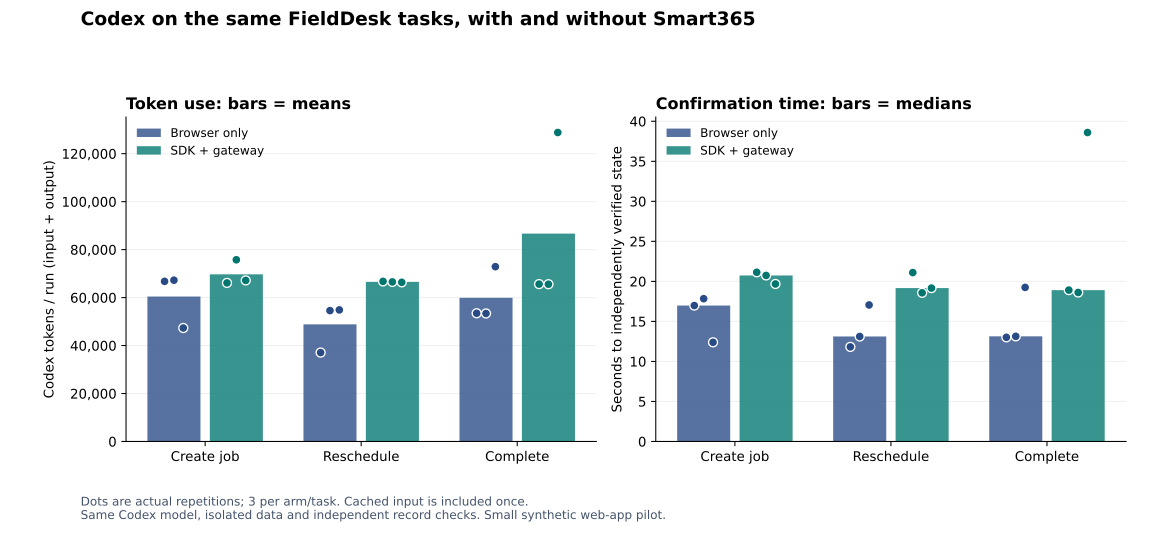
Every recorded trial
| Task / repeat | Arm | Verified | Tokens | Run + state check | Tool calls |
|---|---|---|---|---|---|
| create-job / 1 | control | Yes | 66,764 | 16.98s | 7 |
| create-job / 1 | assisted | Yes | 66,116 | 21.14s | 6 |
| reschedule-job / 1 | assisted | Yes | 66,747 | 21.10s | 6 |
| reschedule-job / 1 | control | Yes | 37,072 | 11.82s | 4 |
| complete-job / 1 | control | Yes | 53,466 | 13.01s | 6 |
| complete-job / 1 | assisted | Yes | 65,619 | 18.91s | 6 |
| create-job / 2 | assisted | Yes | 75,764 | 20.74s | 7 |
| create-job / 2 | control | Yes | 67,247 | 17.84s | 7 |
| reschedule-job / 2 | control | Yes | 54,572 | 13.12s | 6 |
| reschedule-job / 2 | assisted | Yes | 66,524 | 18.57s | 6 |
| complete-job / 2 | assisted | Yes | 65,570 | 18.61s | 6 |
| complete-job / 2 | control | Yes | 53,382 | 13.13s | 6 |
| create-job / 3 | control | Yes | 47,323 | 12.39s | 5 |
| create-job / 3 | assisted | Yes | 67,155 | 19.68s | 6 |
| reschedule-job / 3 | assisted | Yes | 66,354 | 19.16s | 6 |
| reschedule-job / 3 | control | Yes | 54,861 | 17.06s | 6 |
| complete-job / 3 | control | Yes | 72,884 | 19.25s | 8 |
| complete-job / 3 | assisted | Yes | 128,819 | 38.60s | 10 |
Method, attribution and limits
- 3 repeats × 3 tasks × 2 arms. 18 recorded runs; the planned set is complete.
- Both arms use Codex CLI 0.159.0-alpha.3, gpt-5.3-codex, low reasoning effort, fresh sessions and isolated seeded trial accounts. Arm order alternates by task and repetition.
- Tasks: create a correctly assigned job, reschedule an existing job while preserving other fields, and complete a job with an exact note. Browser fills can batch multiple fields, so the control does not incur artificial one-field-per-tool overhead.
- Success is checked by a separate authenticated database-state read: exact requested fields, all unrelated jobs preserved, expected record count, and exactly one business write. Chat messages claiming success are not evidence.
- Both sites share identical business UI and backend source. The assisted arm loads the licensed deployed SDK, then Codex can discover, inspect and execute registered Smart365 capabilities through the real permission-checked gateway.
- The timed workflow starts with opening the site in both arms. Confirmation time includes Codex runtime, browser/SDK initialization, model reasoning, tool requests and an independent state check. Account reset, consent/key setup and revocation are excluded and retained as separate setupMs values.
- Browser presentation uses local HTTP to avoid changing this workspace’s Chromium TLS trust store. Both use fixed HTTPS proxies to their own hosted Vercel backends; Smart365 provider calls execute remotely. TLS verification remains enabled. This is not a direct remote-browser latency test.
- Tokens are actual CLI turn.completed usage. Total = input + output; cached input is a subset of input and is not added again. Output includes reasoning tokens when the provider includes them. Missing usage remains null, not zero. No billed dollar-cost measurement is available.
- The CLI emitted a model-metadata fallback warning for this API provider in both arms; the same fixed requested model and CLI configuration were used throughout.
- Model tool-call counts include metadata-resource lookups. Smart365 performs a lookup, write and independent provider read; explicit verify calls may add further reads. These provider calls are recorded separately, so fewer model calls do not imply fewer total API calls.
- Permission checks also verified that missing write scope, changed-input replay and revoked agent keys are rejected. Replaying the same operation produces one saved business write.
- One main trial reused a static idempotency key from an earlier trial under the same Smart365 user. The gateway returned the older run; a fresh provider read detected that the current trial was not completed. Codex recovered with a new key and exactly one write. Its extra tokens and time remain included. This exposes a connection-change/idempotency design issue: runs should bind to the connected account generation, and keys should include a unique request identifier.
- Provider-call totals count incremental calls per unique execution ID, preventing the reused older execution from being counted twice. They cover the measured task set, not SDK telemetry or all server-internal requests.
- Engineering preflights are archived separately. They exposed a scoped tool-approval problem, MCP proxy inheritance, and ambiguous note punctuation; those were fixed before the main set. All main-set failures remain included. No reruns replace main-set records.
- Small controlled pilot on a synthetic app; not a universal browser/native-app benchmark.
- Assisted arm adds registered structured capabilities and API execution; SDK-alone effect is not isolated.
- No raw-API-only third arm, so gains cannot be attributed uniquely to Smart365 versus direct APIs.
- Model caching, cloud cold starts and network latency can affect timing.
- No billed-cost claim; token totals include cached input once.
- This benchmark does not test the proposed native desktop/iOS adapters, arbitrary external agents or company entitlements. It measures the current web integration, not the entire future platform.
The benchmark is a separate FieldDesk project with fictional records. No benchmark application code was added to the Smart365 repository.